Skip to content

Haben Eyasu

AI & Data Engineer

I build data-driven AI systems, from production pipelines and machine learning models to privacy-first, on-device LLM applications.

AI / MLData EngineeringLLM SystemsSoftware Engineering
inputhiddenoutput

Selected Work

Selected Work

Data-driven AI systems and production software — from on-device inference to ETL pipelines serving real users.

01

On-Device AI · React Native · LLM Systems

Zayla

Active
React NativeTypeScriptllama.cpp (llama.rn)GGUFONNX Runtime

An offline-first mobile AI assistant that runs LLM inference locally on constrained Android hardware — zero servers, zero accounts, zero data collection.

System flow

01Mobile UI
02Model Manager
03GGUF Model
04llama.cpp
05CPU / GPU
06Local Inference
07Response UI

App screenshot
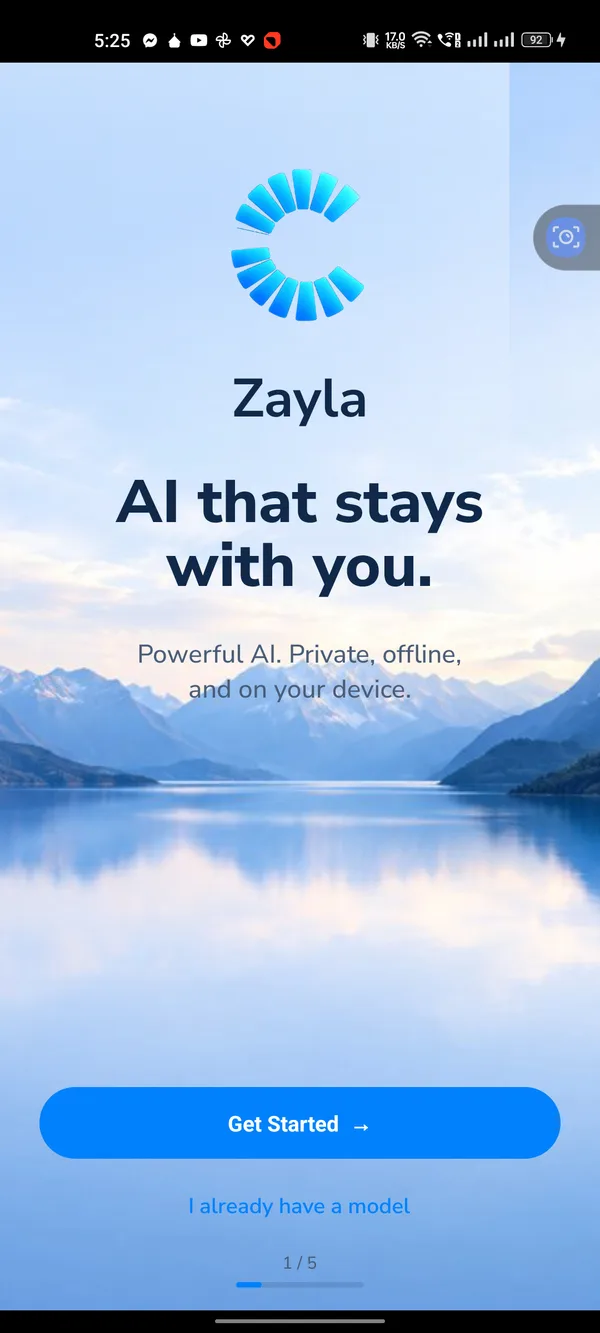
Zayla app onboarding screen

Metrics

Model
User-selected GGUF (device-scored)
Quantization
Q4_K_M / Q5_K_M
RAM usage
Model-dependent — scored pre-download
Performance
Benchmarking in progress (live in-app llama-bench)
Data collection
Zero — fully offline

Engineering challenge

Running useful LLM inference locally while staying inside mobile memory, thermal and compute constraints — without a server to fall back on.
02

On-Device AI · LLM Systems · Low-Resource NLP

Africa LLM (AFRI-LLM-CODEX)

Active
Pythonllama.cppGGUFGBNF GrammarsNLLB-200

A fully offline coding assistant built for the hardware Africa actually has — CPU-only, 8GB RAM, zero network calls — submitted to the Africa Deep Tech Challenge 2026.

System flow

01Codebase
02DS-Code Graph (Context)
03Quantized LLM (GGUF)
04Grammar-Constrained Decoding
05JSON Patch / Explanation
Debug / Patch Mode
Interactive Mode
Pedagogical Tutor Mode

App screenshot

afri-llm-codex — run_inference.py

$ python run_inference.py --prompt "Fix the memory leak"

> peak RAM: 1.26 GB · 10.71 tok/s (CPU)

> arc_easy accuracy: 0.68 (n=50)

> grammar-constrained JSON patch, 100% offline

Q5_K_M
Q4_K_M
IQ4_XS

Metrics

Model
Qwen2.5-Coder-1.5B (Q5_K_M, 1.78B params)
Throughput
10.71 tok/s (CPU)
Peak RAM
~1.26 GB
Accuracy
0.68 arc_easy (n=50)
Languages
8, chrF++ 22.6–58.0

Research question

Can a single quantized model plus a from-scratch dependency-graph context engine deliver reliable, grammar-constrained code assistance entirely offline, on hardware with no reliable power or internet?

03

Data Engineering · ETL · Full-Stack Platform

Smart Billing System

Completed
PythonPostgreSQLFastAPIDjangoReact

A full-stack billing platform built around a high-volume ETL pipeline — ingesting, validating and serving 1.2M+ transaction records through a production-shaped API and dashboard.

System flow

01Transaction Data
02ETL Pipeline
03PostgreSQL
04REST API
05React / Streamlit UI

App screenshot

smart-billing — etl_pipeline.py

$ python etl_pipeline.py --source billing_raw --target postgres

> ingested 1,200,000+ transaction records

> processing speed: +34% vs. baseline

Baseline
Optimized

Metrics

Records processed
1.2M+ transactions
Processing speed
+34% vs. baseline
Backend
FastAPI + Django
Database
PostgreSQL
Frontend
React + Streamlit

Engineering angle

How do you take a pipeline built to move 1.2M+ transaction records and turn it into a system real users — billing, customer management, payments — can depend on?

04

Full-Stack Web · EdTech · Ongoing Maintenance

Mahder Academy

Active
Next.jsNode.jsMongoDBAuth & PaymentsCI/CD

A live e-learning platform I co-founded and built end-to-end — now serving 100+ students across 11+ courses, with ongoing maintenance and support.

System flow

01Student
02Next.js App
03API / Auth Layer
04Database
05Course Delivery

App screenshot

mahderacademy.com
Mahder Academy

Think Better. Speak Smarter.

Explore Courses →

Intermediate
Intermediate
Enroll →
Upper-Intermediate
Upper-Intermediate
Enroll →
Beginner (Kids)
Beginner (Kids)
Enroll →

Metrics

Role
Co-founder, full-stack build + maintenance
Students
100+
Courses
11+
Status
Live, in production
Support
Ongoing (solo)

Engineering angle

What does it take to keep a real production education platform reliable — not just launched — across new features, content changes and everyday support requests?

Earlier Work

Computer Vision · Deep Learning · Agri-Tech

Plant Disease & Fruit Ripening Detection

An earlier computer-vision project — detecting plant disease from leaf imagery and estimating fruit ripeness from visual cues — for greenhouse monitoring.

CNNOpenCVTransfer LearningImage Classification

Engineering Depth

Engineering Depth

Grouped by discipline — only technologies I've actually shipped with.

AI / Machine Learning

  • Python
  • PyTorch
  • TensorFlow
  • scikit-learn
  • XGBoost
  • OpenCV
  • NumPy
  • Pandas

Data Engineering

  • Python
  • SQL
  • PostgreSQL
  • ETL / ELT Pipelines
  • Azure
  • AWS
  • GCP
  • Docker

LLM Systems

  • LangChain / LangGraph
  • RAG
  • LLM Fine-Tuning (QLoRA)
  • Prompt Engineering
  • llama.cpp
  • GGUF
  • Quantization
  • On-Device Inference

Software Engineering

  • TypeScript
  • React
  • React Native
  • FastAPI
  • Django
  • Node.js
  • Git
  • Linux

Experience

Experience

  1. Co-founder & Full-Stack Developer

    2024 — Present

    Mahder Academy · Remote

    • Designed and built a live e-learning platform end-to-end — frontend, backend API, and database — now serving 100+ students across 11+ courses.
    • Own the platform after launch: uptime, bug fixes, and new features, working solo against real user feedback and usage data.
    Next.jsNode.jsMongoDBFull-Stack
  2. Software & Data Infrastructure Engineer

    Jun 2024 — Apr 2025

    Eritel Telecom · Asmara, Eritrea

    • Engineered automated ETL pipelines in Python and SQL to process large-scale industrial datasets, increasing downstream data reliability by 28% and eliminating manual transformation steps.
    • Architected scalable data models on Azure with high-concurrency support, enabling AI-assisted internal reporting tools used across multiple business units.
    • Designed and shipped automated data validation and integrity checks that cut manual troubleshooting time by 33%, owning the feature from spec through production monitoring.
    • Refactored high-volume datasets into query-optimised schemas, reducing query response times for data-heavy applications.
    PythonSQLAzureETLData Modelling
  3. Full-Stack & Analytics Engineer

    May 2023 — Feb 2024

    Eritrea Electric Corporation · Asmara, Eritrea

    • Built and shipped full-stack dashboards and reporting pipelines end-to-end, enabling real-time visualisation of power distribution data for grid operations teams.
    • Applied statistical modelling and trend analysis (deterministic and stochastic methods) to improve demand-forecasting accuracy by 23%, supporting grid capacity planning.
    • Designed clean data architectures and automated processing scripts as the foundation for later machine-learning initiatives.
    • Analysed large-scale consumption patterns, contributing to a 14% reduction in operational inefficiencies.
    PythonForecastingData PipelinesDashboards
  4. Research Assistant, Machine Learning

    2022 — 2023

    RIC Lab, Dept. of Computer Science and Engineering · Asmara, Eritrea

    • Developed named-entity recognition (NER) and part-of-speech (POS) tagging resources for Tigrinya and Ge'ez — two under-resourced Semitic/Ethiopic languages with minimal prior NLP tooling.
    • Designed annotation schemes and tagging pipelines addressing the near-total absence of labelled data, laying groundwork later extended into independent NLP projects.
    NLPLow-Resource LanguagesNERAnnotation

Research

Research

Low-resource NLP for Tigrinya and Ge'ez, and applied LLM experimentation — with links to the actual repositories.

Low-Resource NLP for Tigrinya & Ge'ez

Research Project

2022 – 2023 · RIC Lab, Dept. of Computer Science and Engineering

Named-entity recognition and part-of-speech tagging for two under-resourced Ethiopic-script languages with almost no prior NLP tooling.

  • Designed annotation schemes and tagging pipelines from a near-total absence of labelled data
  • Later extended with weak supervision and transformer-based sequence labeling
Repository

Tigrinya Tokenization (BPE)

Repository

Ongoing

A byte-pair-encoding tokenizer built specifically for Tigrinya, reducing token fragmentation and out-of-vocabulary rates for downstream NLP pipelines.

Repository

Multilingual Health QA — Zindi Competition

Experiment

2025

Fine-tuned CohereForAI/aya-23-8B via two-phase QLoRA (Kaggle, T4×2 GPUs) for multilingual health question answering under a fixed compute budget.

  • First submission scored 0.6559 ROUGE-L

Agentic RAG Research Assistant

Repository

2025 – Present

A LangGraph pipeline using multi-step tool calls and vector-store retrieval, with an evaluation loop to check answer quality systematically rather than trusting model output blindly.

Repository

About

About

I'm an AI and Data Engineer with a software engineering background, currently pursuing an MSc in Artificial Intelligence at the University of Jyväskylä.

I build data pipelines, machine learning systems, and AI products, with recent work focused on low-resource NLP, on-device LLM inference, and privacy-first AI applications.

My engineering work spans Python, SQL, Azure, PyTorch, React Native, Docker, and llama.cpp.

Trajectory

  1. Software Engineering
  2. Machine Learning Research
  3. Data Engineering
  4. LLM Systems
  5. AI & Data Engineering

Contact

Get in Touch